Make the character once, and look at her before you make anything else. Then make every other shot from that frame — never by describing her again in words. Put literal text on a typeset card, never in an image prompt. Give exactly one shot generated motion: the one where she has to actually move. Music, render, done.
Why a fuel station
Ask any current image model for an anime still and it hands you a good one first try. Cel shading, hard rim light, a hand-painted background. That is close to a default mode now, which means polish is not what separates your reel from anyone else's — everybody's first attempt is already polished. So the interesting move is to spend the aesthetic somewhere it does not belong: anime's fantasy-and-romance visual language applied to the least glamorous place in town, and to the small arithmetic people do at the pump — watching the number climb, stopping it on something round. Nobody has made that beautiful before, and everyone has stood there.
Image generation is non-deterministic. Run these prompts and you will get your character, not ours — a different face, a different drape of the jacket, a different night. That is not the prompt failing; it is what these models are. What reproduces is the method, not the pixels.
Step 1 — make her first, and look at her
Upload nothing. Open Poppify in chat and say what you're making, then hand over the first prompt whole:
Make me an anime series — "Night Shift", a quiet story set at a roadside
fuel station at 3am. Vertical, 9:16.

Before anything else, generate ONE still of the main character, from this
prompt exactly:

Anime still, night, cel-shaded with hand-painted background. A young woman
behind the counter of a small roadside fuel-station kiosk, lit almost
entirely by green-white fluorescent canopy light falling from above. She
wears a company windbreaker two sizes too big, sleeves past her hands; one
earphone in, the other hanging loose against her collar. Hair tied up
loosely, strands escaping. Tired, calm, unbothered — not sad, not smiling.
Medium close-up, eye level, shallow depth of field. Far behind her through
the kiosk window, completely out of focus, the soft glow of a tall
illuminated price sign — unreadable bokeh. Limited palette: green-white
fluorescent, deep night blue, warm amber highlight. Hard rim light on her
shoulder. Film grain. No text, no letters, no numbers anywhere in the
image. Vertical 9:16.

Then stop and show me the image before making anything else.
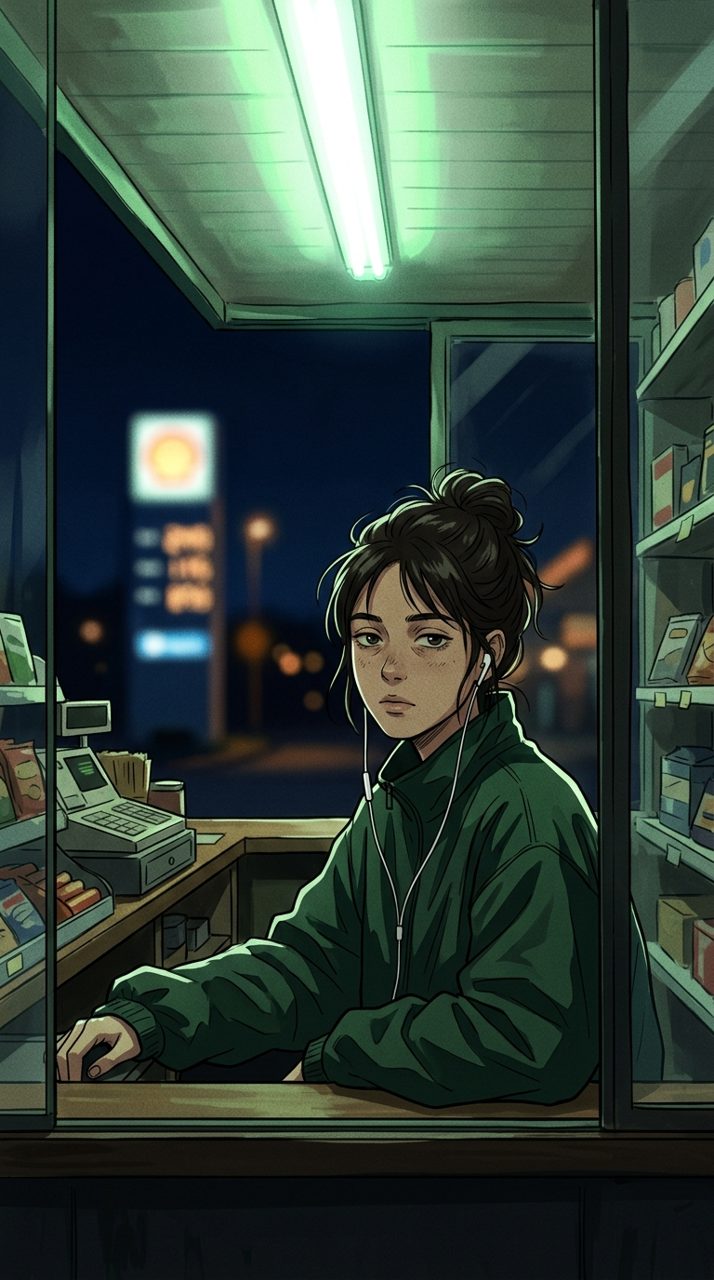
Now actually look at her before you go any further. Every shot after this one is generated from this frame, so whatever is wrong here is about to be wrong four more times. That "stop and show me" line is the entire point of step 1.
Notice what the prompt is made of: coarse, high-contrast anchors — one oversized jacket, one hanging earphone, one green-white light. Those survive regeneration. Fine facial detail does not, and it doesn't matter, because nobody recognises a character by her eyelid. They recognise the silhouette.
Step 2 — make every other shot from her, not from a description
This is the move the whole method rests on. Do not describe her again. Tell Poppify to use the frame it just made as the reference for each new shot, and let each prompt point back at it:
Use that first image as the reference for the next three shots — same
character, same style, same night. Generate them from these prompts,
exactly:

SHOT 2 — the forecourt, wide
Same anime style, same cel-shading and hand-painted background as image 1,
same night, same green-white fluorescent palette. WIDE establishing shot of
the whole fuel station forecourt at 3am, seen from across the empty road.
Bright canopy lights flooding an empty concrete apron; a single small car at
the far pump, tiny in frame; the lit kiosk window glowing at the back where
the woman from image 1 sits, small and distant. Tall illuminated price sign
on a pole at the left edge, its numbers soft and out of focus. Wet asphalt
reflecting the canopy light. Deep night blue sky, no stars. Empty, quiet,
enormous. No text, no letters, no legible numbers anywhere. Vertical 9:16.

SHOT 3 — at the pump
Same anime style, same cel-shading, same night and green-white fluorescent
palette as image 1. Tight low-angle shot of a gloved hand gripping a fuel
nozzle in the pump socket of a car, seen from the side. The nozzle, the hose
and the car's paintwork fill the frame. The pump's display housing is turned
completely away from the camera and is not visible at all — there is NO
screen, NO panel, NO dial and NO signage anywhere in the frame. Behind, far
out of focus, the warm glow of the lit kiosk window. Shallow depth of field,
intimate, cold night air. Absolutely no text, no letters, no numbers, no
symbols, no lettering of any kind anywhere in the image. Vertical 9:16.

SHOT 4 — walking away at dawn
Same young woman from image 1 — same oversized green company windbreaker,
same loose tied-up hair, same earphone cord — now outside, seen from behind
and slightly to the side, walking away from the fuel station at dawn. Small
canvas bag over one shoulder, hands in pockets, sleeves over her hands. She
walks past a small parked car in the foreground without turning her head
towards it. Early dawn light: the night blue lifting to cold pale grey at
the horizon, the canopy lights behind her still on and now weaker than the
sky. The tall price sign glows on its pole behind her, its figures soft and
unreadable. Long empty road ahead. Same anime cel-shaded style and
hand-painted background as image 1. Quiet, ordinary, not tragic. No text,
letters or legible numbers anywhere. Vertical 9:16.
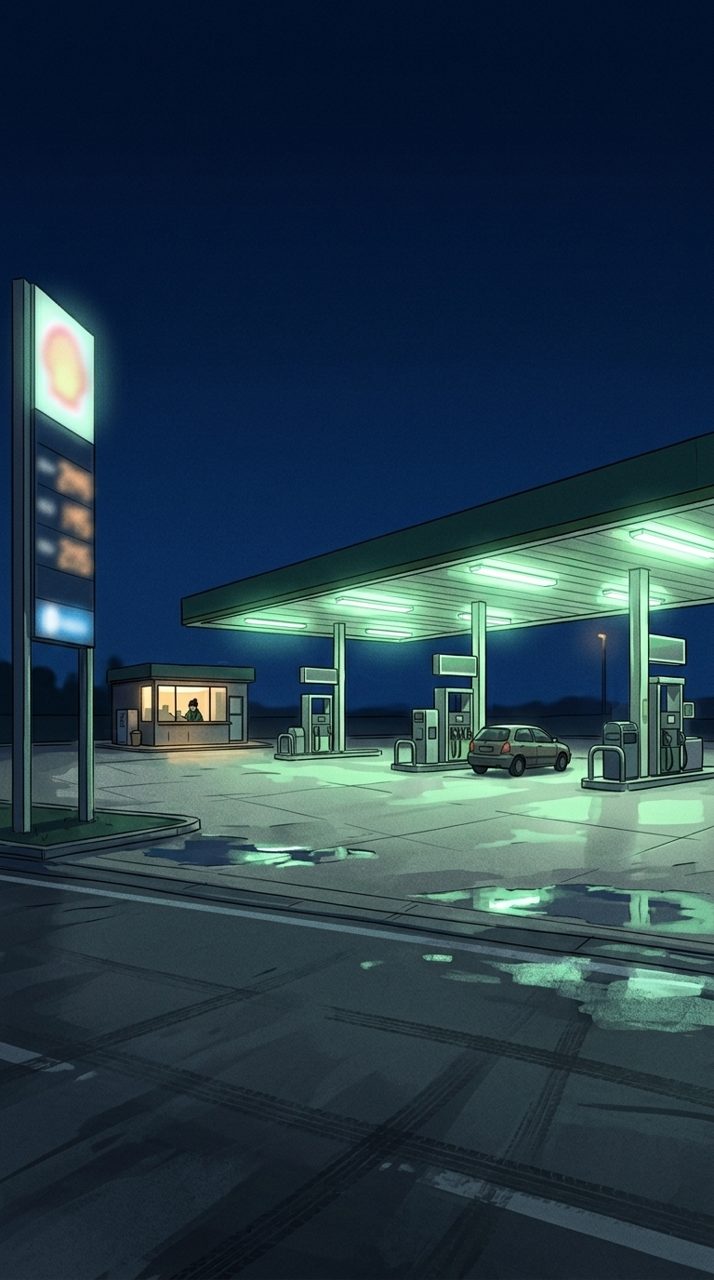
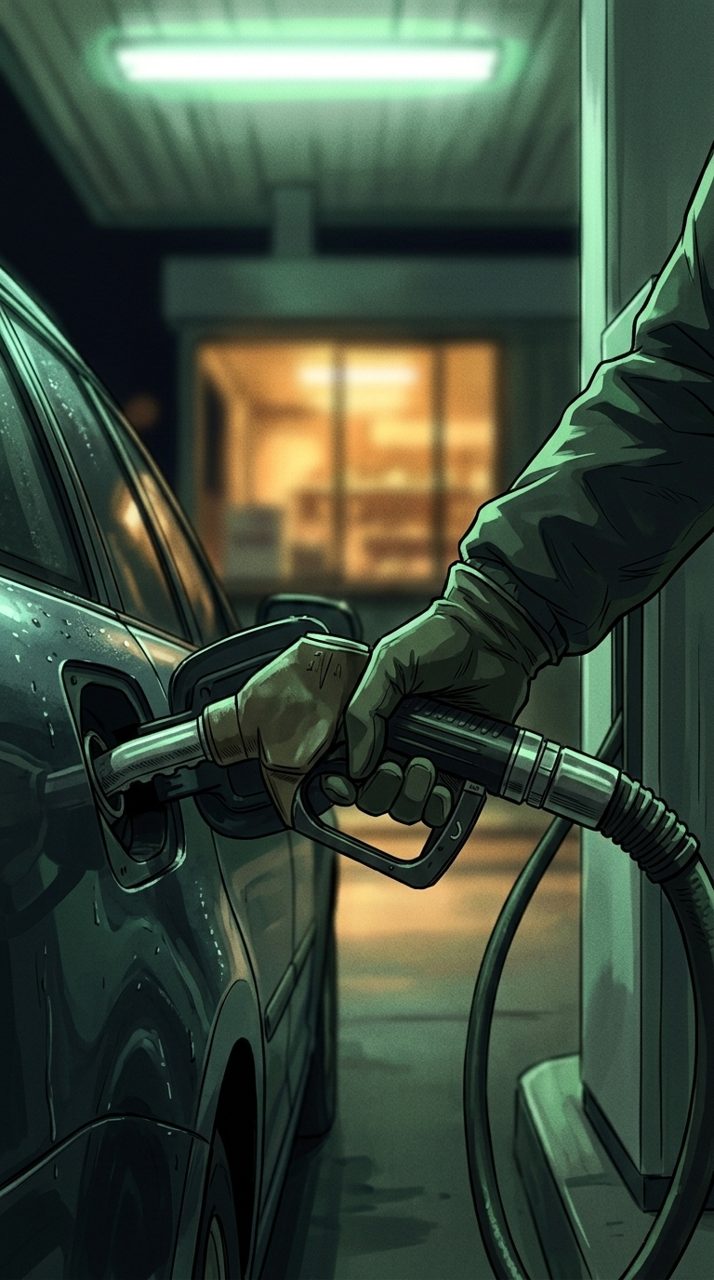
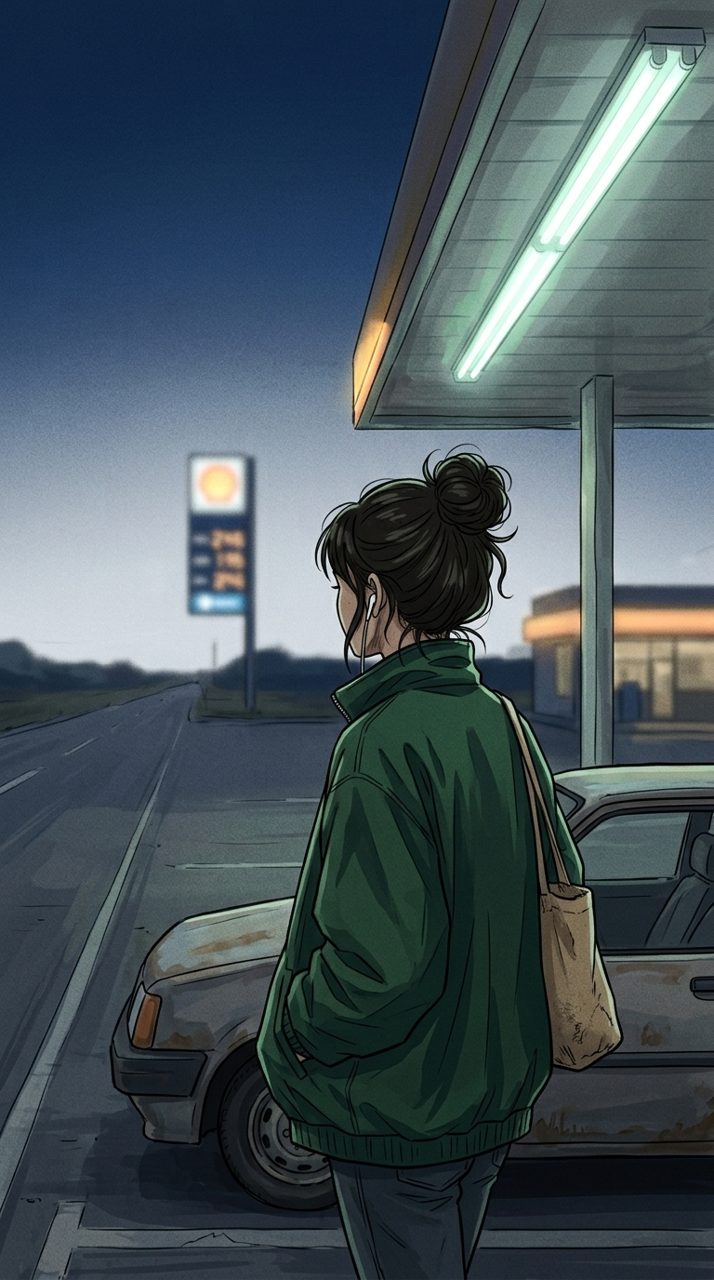
Each prompt opens by pointing back at image 1 — "same anime style", "same young woman from image 1" — but those words are not what holds her together. The reference frame is. The sentences only tell the model which parts of image 1 to carry; they are not rebuilding her from scratch, which is what drifts.
Step 3 — the end card, set in real type
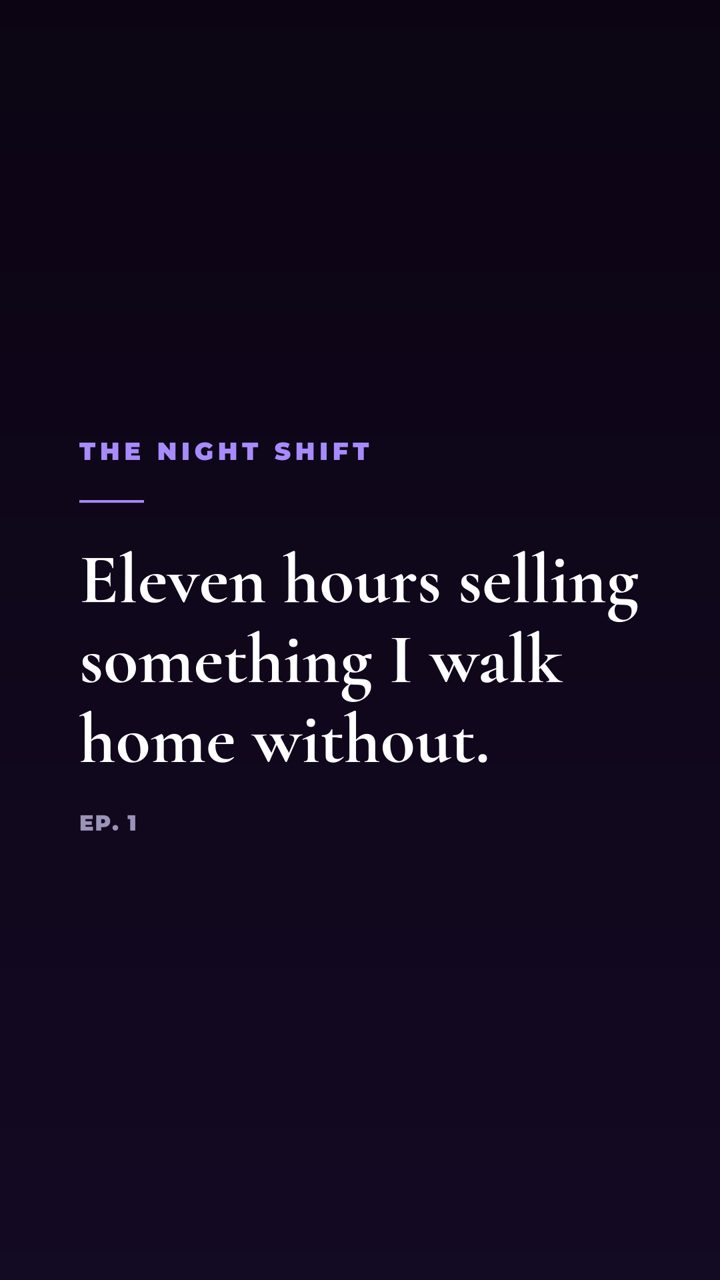
Never ask an image model for words that have to be correct. Ask for a card instead — Poppify typesets it server-side with real fonts (add_text_card), so the string is exact on the first attempt and there is no generation involved at all:
Add a final card. Eyebrow "THE NIGHT SHIFT", the line
"Eleven hours selling something I walk home without.",
footer "EP. 1". Midnight theme, left aligned.
Step 4 — one shot moves
Generated motion is the slow part of a build like this and is almost never wanted on more than one shot. Put it where the subject has to be alive: the frame the reel opens on. Everything else gets camera movement over a still, which on a wide establishing shot is indistinguishable from the real thing. Write the action as small, involuntary movement — breath, a blink, something crossing the background. Not performance:
Make the first shot live motion, with this action:

She blinks slowly once and exhales; her breath fogs faintly in the cold
air. A moth crosses the fluorescent tube behind her. Almost imperceptible
push-in. She does not speak and does not smile.
Step 5 — music, then render
Ask for the soundtrack in mood, not in genre names. Then tell it to go:
Find music for this — sparse piano and cello, slow, patient, nordic noir.
Something melancholy but not sad. Then render it.
Ours matched a library track called Comfortable Melancholy: piano and cello at 70bpm, which is roughly the tempo of someone who has been awake since nine. The render takes a minute or two, and what comes back is a link to the finished MP4 — the one playing at the top of this page.
Three things that will save you a re-run
1. You cannot ask for illegible text
Shot 3 was originally planned as an over-the-shoulder view at the pump with the display panel as the bright centre of the frame, and the prompt asked for its figures to be "blurred and unreadable". What came back had crisp, confident, entirely legible text on the panel. It read Pront 4520 · Diay's 6000 · 2200.
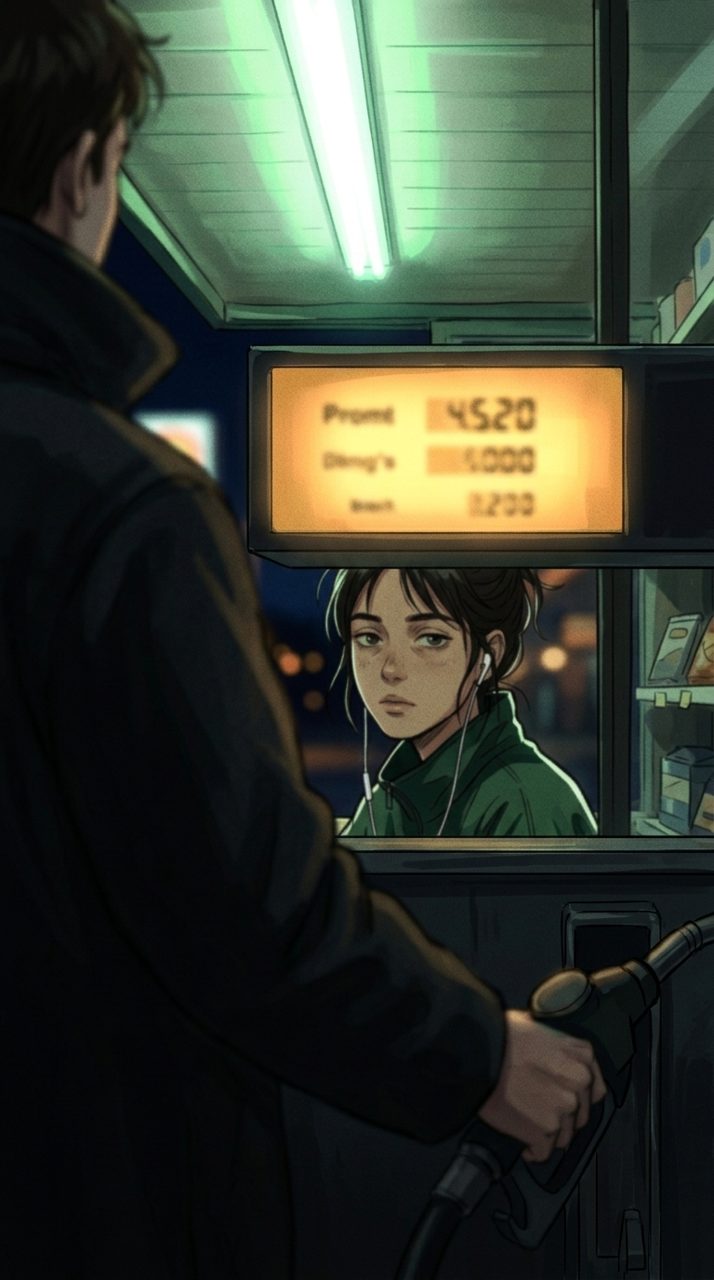
The prompt had also said "no text anywhere in the image". That instruction was there and it lost the argument, because the composition had asked for a screen, and a screen is a thing with writing on it.
Blur is a request; absence is a composition. "Blurred", "soft", "out of focus", "unreadable" — every one of them still asks for figures, and the model draws them, sharply and wrongly. The only reliable fix is to take the text-bearing surface out of the frame: turn it away, crop it, put it behind something. That is what the shot 3 prompt above does, and it says so four times in four vocabularies, because one negation is not enough when the composition is pulling the other way. It also produced a better shot than the original plan — a hand and a nozzle instead of a wide view with a screen in it.
If you genuinely need a number on screen, the answer is not a better prompt. It is a text card, or an overlay you control.
2. The live shot brings its own camera move
On a slide with a live clip, the renderer deliberately adds no camera movement of its own. The clip already contains a move, and layering a second one on top re-frames a picture that is already moving — it over-zooms and throws away the composition the clip was generated with. So any push-in you want on that shot has to be written into the action line. That is why ours ends with "almost imperceptible push-in". Asking for a camera effect on a live slide does nothing.
3. Make the character before you make anything else
Shot 1 is the reference for everything that follows, and for every later episode too. Generate one frame, look at it, then go on. We followed that at the top level and skipped it one level down — shots 2, 3 and 4 were fired off together, which is how a garbled pump display got discovered after the fact instead of before. Check each frame against the reference before committing to the next one.
Then it becomes a series. The character is constant, the guest at the pump rotates, the number on the sign changes — and because the reference still and the soundtrack already exist, every later episode starts at step 2.
Frequently asked
How do you make an AI anime video?
Generate one still of your character and look at it before making anything else, because it defines her for every later shot. Generate every other shot from that frame rather than re-describing her in words. Put literal text on a typeset card, never in an image prompt. Give exactly one shot generated motion — the one where the subject has to move — then add music and render.
How do you keep an AI character consistent across shots?
Pass the first frame itself as the reference on every later generation instead of re-describing the character in prose, and design her out of coarse anchors that survive regeneration: one silhouette, one garment, one prop, one light source. A windbreaker two sizes too big and green-white fluorescent light come back reliably. The exact shape of an eyelid does not.
Why does text come out garbled in AI images?
Image models draw typography as shapes, not as language, so a sign or screen in frame returns confident-looking nonsense. Asking for it to be blurred or unreadable does not help — that still asks for figures. Remove the text-bearing surface from the composition, and put any string that must be correct on a typeset card.
Can I name an anime studio or character in a prompt?
No — that gets the generation refused as third-party IP. Describe attributes instead, which is both permitted and more precise: cel-shaded, hard rim light, hand-painted backgrounds, limited palette. That is what you wanted from the studio name anyway.
Related reading
- Pillar: AI Video Generator for Small Business — the three categories of tool, and why composing stills is a different product from generating footage.
- How to Use AI for Video Generation: Five Rules — the practice guide this method is an application of.
- How to Make a Before-and-After Reel from Photos — the other format that lives or dies on shot discipline.